Repository navigation
CI: de-flake master (perf gate, fidelity backfill, NetworkManager race, macOS goldens) - #6068
Conversation


…tests

- perf gate: an improvement past the baseline is reported, not failed; a
  row tolerance only widens the policy; policy 20% time / 25% RAM.
- fidelity: goldens of rows scoped to other platforms are not missing_actual
  (DesktopSeparator failed every Windows/GNOME run).
- macOS: reseed DesktopWidgetsTheme_{dark,light} and VectorMapShapes.
- NetworkManager: never run one ConnectionRequest on two workers (a retry
  from a response-code listener raced its own attempt); tests stop the
  workers they reset instead of leaking them.
- CommonTransitionsTest: pin the animation clock.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
…ments

Improvements no longer fail a pull request, so a win must not be giveable
back unnoticed: each gate uploads perf-results-<platform>, and the nightly
fold job lowers a row that every one of >=3 master runs in the last seven
days beat by more than half its tolerance, to the worst of those runs.

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>

|
@codex review |

Codex Review SummaryThis comment shows the latest Codex review activity on this pull request.
ℹ️ About Codex in GitHubYour team has set up Codex to review pull requests in this repo. Reviews are triggered when you
Codex reacts with 👀 while any review is running, comments if it has suggestions, and reacts with 👍 once all reviews finish with no findings. |


There was a problem hiding this comment.
💡 Codex Review
Here are some automated review suggestions for this pull request.
Reviewed commit: 78801669bc
ℹ️ About Codex in GitHub
Your team has set up Codex to review pull requests in this repo. Reviews are triggered when you
- Open a pull request for review
- Mark a draft as ready
- Comment "@codex review".
If Codex has suggestions, it will comment; otherwise it will react with 👍.
Codex can also answer questions or update the PR. Try commenting "@codex address that feedback".
…ldens the spec does not know

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>

Flutter vs Codename OneSame application, built both ways: Flutter's AOT compile of the gallery, and the identical Dart source transpiled to Java on Codename One. Lower is better for every metric, so a ratio above 1.00x means Codename One is ahead by that factor. javascript9 interleaved rounds; host load 2.43, 1.25, 0.52
Compute -- the VM workloads (
Gate: within tolerance against
Codename One wins 3 of 3 measured metrics across 1 platform(s). |
|
Compared 12 screenshots: 12 matched. |
|
Developer Guide build artifacts are available for download from this workflow run:
Developer Guide quality checks: |
|
@codex review |
There was a problem hiding this comment.
💡 Codex Review
Here are some automated review suggestions for this pull request.
Reviewed commit: da59086d93
ℹ️ About Codex in GitHub
Your team has set up Codex to review pull requests in this repo. Reviews are triggered when you
- Open a pull request for review
- Mark a draft as ready
- Comment "@codex review".
If Codex has suggestions, it will comment; otherwise it will react with 👍.
Codex can also answer questions or update the PR. Try commenting "@codex address that feedback".
Cloudflare Preview
|
Native fidelity (Android, Material 3)54 pairs compared -- median 95.6%, worst 91.3% ( Distribution --
Geometry vs native (bbox offset / size ratio / center offset / corner radius) -- gated separately from the visual score
Side-by-side comparisons (worst first)
|
|
Compared 170 screenshots: 170 matched. Native Android coverage
✅ Native Android screenshot tests passed. Native Android coverage
Benchmark ResultsDetailed Performance Metrics
|
|
Compared 206 screenshots: 206 matched. |
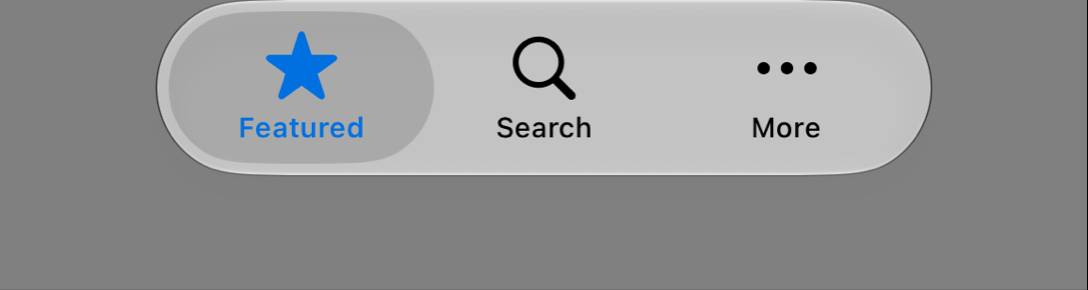
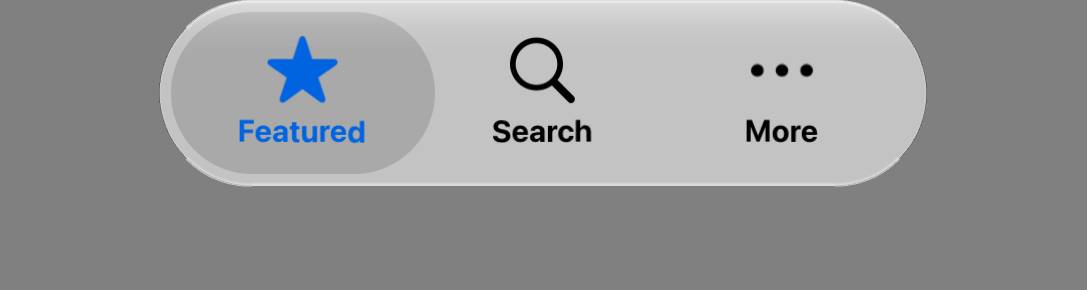
Native fidelity (ios-27-metal)68 pairs compared -- median 94.6%, worst 74.5% ( Distribution --
Geometry vs native (bbox offset / size ratio / center offset / corner radius) -- gated separately from the visual score
Side-by-side comparisons (worst first)
|


|
Compared 185 screenshots: 185 matched. Benchmark ResultsDetailed Performance Metrics
ParparVM vs HotSpot (JDK 25): Windows x64Runner CPU: Intel64 Family 6 Model 207 Stepping 2, GenuineIntel (baseline 1 performance regression:
Ratios are ParparVM / JDK 25: below 1.00x ParparVM is faster (time) or smaller (RAM). Median of 5 interleaved, paired rounds; every run's output was verified. A ratio more than 20% (time) / 25% (RAM) above its baseline in
A change that moves performance ON PURPOSE records the new baseline in Result: performance regression |
|
Compared 185 screenshots: 185 matched. Benchmark ResultsDetailed Performance Metrics
|
✅ Continuous Quality ReportTest & Coverage
Static Analysis
Generated automatically by the PR CI workflow. |
…ack; add test headers; calibrate JS size

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
|
@codex review |
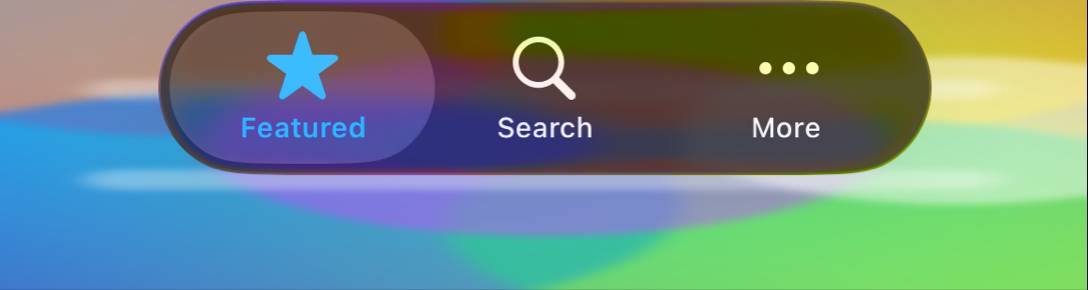
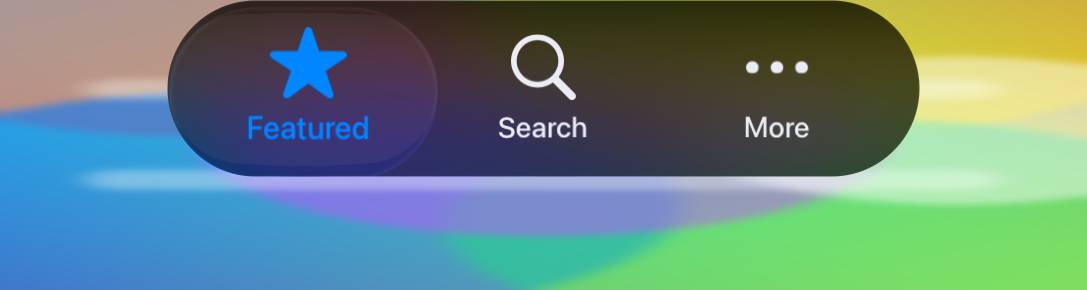
Native fidelity (iOS Modern, Metal)68 pairs compared -- median 95.0%, worst 83.5% ( Distribution --
Geometry vs native (bbox offset / size ratio / center offset / corner radius) -- gated separately from the visual score
Side-by-side comparisons (worst first)
|


There was a problem hiding this comment.
💡 Codex Review
Here are some automated review suggestions for this pull request.
Reviewed commit: 9f29350df1
ℹ️ About Codex in GitHub
Your team has set up Codex to review pull requests in this repo. Reviews are triggered when you
- Open a pull request for review
- Mark a draft as ready
- Comment "@codex review".
If Codex has suggestions, it will comment; otherwise it will react with 👍.
Codex can also answer questions or update the PR. Try commenting "@codex address that feedback".
|
Compared 185 screenshots: 185 matched. ParparVM vs HotSpot (JDK 25): Linux x64Runner CPU: AMD EPYC 7763 64-Core Processor (baseline Ratios are ParparVM / JDK 25: below 1.00x ParparVM is faster (time) or smaller (RAM). Median of 5 interleaved, paired rounds; every run's output was verified. A ratio more than 20% (time) / 25% (RAM) above its baseline in
Result: no regression |
|
Compared 185 screenshots: 185 matched. ParparVM vs HotSpot (JDK 25): Linux arm64Runner CPU: Neoverse-N2 (baseline Ratios are ParparVM / JDK 25: below 1.00x ParparVM is faster (time) or smaller (RAM). Median of 5 interleaved, paired rounds; every run's output was verified. A ratio more than 20% (time) / 25% (RAM) above its baseline in
Result: no regression |
…ine a one-run Windows recursion row

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
|
@codex review |
|
Codex Review: Didn't find any major issues. 🚀 Reviewed commit: ℹ️ About Codex in GitHubYour team has set up Codex to review pull requests in this repo. Reviews are triggered when you
If Codex has suggestions, it will comment; otherwise it will react with 👍. Codex can also answer questions or update the PR. Try commenting "@codex address that feedback". |


Master has been red mostly on the ParparVM performance gate, plus a few deterministic or racy failures.
Performance gate
perf-results-<platform>. Theperf-baseline.ymlfold job runsvm/selfhost/tighten-perf-baseline.pyover master's last seven days of results. A row that at least three runs judged against its current value all beat, by more than half its tolerance (and by the RAM floor), is lowered to the worst of those runs.Other fixes
NetworkManager: aretry()from a response-code listener could run the sameConnectionRequeston two workers at once, losing the first attempt's trace spans. This was the cause of the intermittentTelemetryTestfailure. Separately,NetworkManagerTestandWebServiceProxyCallTestnow shut down the workers they reset instead of leaking them.CommonTransitionsTest: pins the animation clock.platforms: macos) are no longer reported asmissing_actual. That broke every Windows and GNOME run onDesktopSeparator.DesktopWidgetsTheme_{dark,light}andVectorMapShapes. The diffs were the same on every master run: the widgets page moved about 2px, and the map drops one edge label.Translator RAM ratio (0.43 to ~0.51)
This tracks the workload, not a single commit. The benchmark translates
vm/JavaAPIplus the translator itself, and that grew from 341 to 427 source files since the first baseline (the translator's own sources went from 61 to 111). The ratio rose 19% over the same period. Per-arm peak bytes are not recorded inperf-results.json, so this is a correlation, not a proof.🤖 Generated with Claude Code